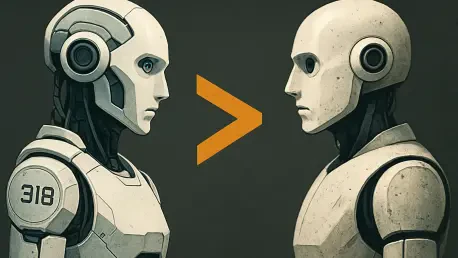
The Karpo Decision 31B model was built using Google’s own open-source Gemma 31B base, effectively leveraging a foundation model to defeat Google’s proprietary Gemini Decision 1. This strategic development marks a profound transition in the artificial intelligence sector, as the era of bloated, general-purpose engines gives way to lean, task-oriented architectures. For years, the dominance of closed-source systems seemed unshakeable, yet MachinePulse has managed to disrupt this hierarchy by focusing on high-frequency judgment rather than verbose text generation. This approach addresses the increasing demand for models that can act as autonomous agents within digital environments, navigating complex workflows with a level of precision that general systems struggle to maintain. By utilizing a public foundation to surpass a private flagship, the developers have proven that the true value of AI now lies in the specialized training and architectural refinement that happens after the initial base model is established.
The Evolution of Machine Intelligence
The broader shift toward specialized decision-making models has been driven by a growing awareness of the limitations inherent in large-scale language systems. While Silicon Valley spent the last few years competing over parameter counts and mathematical reasoning scores, a significant computing power gap began to emerge between theoretical performance and practical application. Traditional large language models often struggle with the “token tax,” where the cost and time required to generate word-by-word responses make them prohibitively expensive for real-time operations. This inefficiency is particularly evident in browser-based tasks, where the sheer volume of data being processed can result in costs that are five times higher than those of standard reasoning challenges. Consequently, the industry has pivoted toward architectures that prioritize immediate decision-making over fluid prose, ensuring that AI can perform as a functional component in an automated pipeline rather than just a chatbot.
Defining the Decision-Making Shift
Technically, the Karpo Decision 31B distinguishes itself through a design philosophy that optimizes for speed and accuracy in classification. Rather than relying on the autoregressive generation common in generative AI, this model calculates the probability of various available options through a single forward inference pass. This structural innovation has allowed it to achieve a median latency of only 94 milliseconds on standard hardware, effectively doubling the speed of previous benchmarks like Jev 1.14. Additionally, the system is capable of evaluating up to 255 different choices simultaneously, which makes it an ideal candidate for managing high-density data environments such as logistics tracking or automated customer service routing. With a remarkably low calibration error of 0.023, Karpo ensures its confidence levels match its actual performance, providing developers with a reliable metric for automated risk assessment that was previously difficult to obtain in open-source formats.
Breaking Down the Karpo Architecture
The Karpo architecture represents a specialized branch of development that emphasizes internal weighting over sequential output. By streamlining the reasoning process, the model avoids the common pitfalls of hallucination often found in generative models tasked with decision-making. MachinePulse has optimized the transformer layers to specifically handle multiclass probability distributions, allowing the model to act as a definitive judge rather than an inquisitive conversationalist. This specialization makes it far more efficient for “agentic” workflows, where the primary objective is to execute a command correctly within a specific software environment. Furthermore, because it is built upon the Gemma foundation, it retains a deep latent understanding of natural language while filtering out the unnecessary overhead of text prediction. This hybrid approach allows for a level of operational focus that proprietary models, which are often stretched thin across hundreds of diverse use cases, have struggled to achieve during recent performance testing.
Evaluating Performance on Global Benchmarks
The success of the Karpo model is best reflected in its current standing on the Decision Index, where it recently secured the top position with a comprehensive score of 73.9. This ranking, which includes over 300 competing models, serves as the definitive benchmark for evaluating how well an AI can handle real-world judgment tasks. A critical aspect of this evaluation is the performance on “blind tests” and private question banks like JevBench, which are designed to prevent models from artificially inflating their scores through data memorization. While many top-tier models typically experience a performance drop of nearly seven points when faced with these unfamiliar datasets, Karpo demonstrated exceptional resilience, losing only 4.3 points. This indicates that the model possesses a genuine capacity for reasoning and generalization across entirely new domains, making it far more versatile for unpredictable enterprise applications than many of its more famous, closed-source competitors.
Leading the Decision Index Rankings
In direct head-to-head comparisons, Karpo 31B has consistently outperformed Google’s Gemini Decision 1 across a range of specialized benchmarks. In the “When2Call” test, which measures the ability of an agent to determine when it should utilize a tool or request additional user input, Karpo achieved a score of 90.4%, leading the Google flagship by a significant 10.5 percentage points. Similar trends were observed in multimodal web navigation tasks, where the model interacted with webpage screenshots to complete complex user requests with a success rate of 90.0% compared to Google’s 86.2%. Even in tasks requiring the interpretation of subtle cultural nuances, such as captioning New Yorker cartoons, Karpo demonstrated a superior success rate of 90.5%. These results highlight a significant narrowing of the gap between open-source foundations and proprietary giants, suggesting that the former can now offer superior performance in the niches that matter most for autonomous automation.
Outperforming Google in Head-to-Head Tests
The results from the “Mind2Web” evaluations further emphasize Karpo’s dominance in complex digital navigation. In these scenarios, models must parse visual information from webpages and make rapid decisions on how to interact with various elements to achieve a specific goal. Karpo’s ability to maintain high precision while managing multiple browser states surpassed the capabilities of Google’s proprietary systems, which often faltered when faced with nonlinear navigational paths. This superior precision also extends to fine-grained classification tasks for major platforms like Amazon, specifically in the ESCI dataset used for product matching and search relevance. By achieving higher accuracy in these specialized domains, Karpo has effectively challenged the narrative that larger, proprietary datasets are required for top-tier performance. Instead, it suggests that the way a model is fine-tuned for decision logic is the primary factor in determining its success in real-world, high-stakes environments.
Real-World Efficiency and Economic Impact
The practical superiority of the Karpo architecture is perhaps most visible in the “City Scanner” challenge, a real-time arena designed to test a model’s efficiency under pressure. In this scenario, the model was tasked with filtering 36 different city events based on a set of five distinct user constraints, ranging from budget limits to social availability. Karpo was able to complete the entire filtering and selection process in just 1.12 seconds with perfect accuracy, whereas general-purpose models were often still in the process of generating introductory text several seconds later. This “tokenless” advantage is a direct result of the decision-making happening within the internal weights of the model rather than through the sequential output of text strings. By eliminating the need for word-by-word generation, the model removes the latency bottleneck that has traditionally hindered the use of AI in high-speed digital environments, enabling a new era of truly responsive automation.
Solving the Token Bottleneck Challenge
Beyond the technical metrics of speed and accuracy, the economic impact of the Karpo family is set to reshape how organizations approach AI deployment. The model offers a revolutionary cost-to-performance ratio, with expenses calculated at approximately $0.025 per thousand decisions. This price point allows a business to execute 40,000 high-level judgments for a single dollar, a figure that was previously unthinkable with high-end proprietary models that charge significantly more for much slower performance. Such a reduction in the “token tax” makes the large-scale implementation of autonomous agents financially viable for small and medium-sized enterprises that were previously priced out of the market. By lowering the barrier to entry, MachinePulse has not only released a powerful tool but has also democratized the ability to build sophisticated, agentic workflows that can operate at scale without incurring the astronomical costs associated with traditional generative AI platforms.
Making AI Deployment Financially Viable
The long-term financial benefits of adopting specialized decision models like Karpo extend beyond immediate operational savings. By reducing the reliance on cloud-based generative APIs, companies can significantly decrease their data egress costs and improve the predictability of their monthly technology expenditures. Furthermore, the efficiency of the 31B model allows it to run on more modest hardware configurations compared to the massive clusters required for general LLMs, further lowering the total cost of ownership. This economic shift encourages a more widespread integration of AI into everyday business processes, from automated compliance auditing to real-time inventory management. As organizations transition their workflows to these specialized systems, the focus will likely move toward optimizing the quality of the data fed into the models, as the cost of processing that data is no longer the primary constraint. This represents a fundamental change in the digital economy, where high-level intelligence is treated as a scalable commodity.
The Future of Specialized AI Models
The rise of Karpo 31B underscores a growing industry consensus that specialization is far more valuable than generalization when it comes to “agentic” workflows. In these environments, the primary objective is for the AI to take action and make accurate choices within a software interface, making the ability to produce human-like prose almost irrelevant. As latency and calibration become the dominant metrics for evaluating AI success, the focus for developers is shifting toward how quickly a model can decide and how reliably it can assess its own accuracy. MachinePulse has further supported this industry movement by releasing a complete family of models, including a lightweight 0.8B version designed specifically for edge devices and mobile hardware. This ensures that high-speed, local decision-making can occur without the need for a constant internet connection, enhancing both the privacy and the reliability of autonomous systems in sectors like healthcare and industrial robotics.
Shifting Toward Agentic Workflows
The emergence of this model represented a strategic pivot in the global technological competition, moving the industry from a “bigger is better” mentality to a “smarter and faster” phase of innovation. By successfully synthesizing high-parameter base models with specialized post-training techniques, developers provided a blueprint for how future systems should be constructed to maximize utility. This shift ensured that the focus remained on reducing operational friction and improving the reliability of autonomous digital assistants. Future considerations for the industry must include a move toward even tighter integration between decision models and specific hardware accelerators to further reduce latency. Organizations should now evaluate their current AI strategies to determine where specialized judgment can replace expensive generative processes. The success of the Karpo project ultimately demonstrated that open-source transparency combined with targeted engineering could set new global benchmarks for what specialized artificial intelligence could achieve.
Reshaping the Global AI Race
The global landscape of artificial intelligence was fundamentally altered by the release of these specialized decision models, which shifted the competitive focus toward efficiency and practical reliability. As enterprises began to prioritize systems that could execute tasks with minimal latency, the influence of massive, all-encompassing models started to wane in favor of more agile solutions. This transition favored developers who could provide transparency and customization, allowing businesses to tailor the decision logic to their specific regulatory and operational requirements. Moving forward, the industry is expected to see a surge in the development of domain-specific decision engines that build upon the open foundations established by models like Karpo. To remain competitive, organizations should prioritize the adoption of models that offer high calibration and low operational costs, ensuring their automated systems remain both accurate and scalable. This evolution toward specialized intelligence has paved the way for a more resilient and efficient digital infrastructure that prioritizes action over conversation.